27.1. Neural network types and architecture#
Terminology#
When describing a neural network algorithm we typically need to specify three key ingredients:
Architecture
The architecture specifies the topology (the number and connectivity of nodes) and parameters that are involved in the network. For example, the parameters involved in a neural network could be the weights that multiply signals between the neurons, including bias weights, and other parameters determining the form of the activition functions.
Activation rule
Most neural network models have short time-scale dynamics. Local (possibly node-specific) rules define how the activities change in response to signals from other nodes. Typically the activation rules are functions of the weights in the network and possibly other activation-function hyperparameters.
Learning algorithm
The learning algorithm specifies the way in which the neural network’s weights are optimized during training. This learning is usually viewed as taking place on a longer time scale than the one of the activity rule dynamics. Usually the learning rule involve iterative updates that depend on the activities of the neurons. It may also depend on target values supplied by a teacher and on the current values of the weights.
Artificial neurons#
The field of artificial neural networks has a long history of development and is closely connected with the advancement of computer science and computers in general. A model of artificial neurons was first developed by McCulloch and Pitts in 1943 to study signal processing in the brain. Their work has later been refined by others. The general idea is to mimic the functionality of the neural network in the human brain. This biological system is composed of billions of neurons that communicate with each other by sending electrical signals. Each neuron accumulates incoming signals which must exceed an activation threshold to trigger the neuron and yield an output. If the threshold is not overcome, the neuron remains inactive, i.e. has zero output.
This behaviour has inspired a simple mathematical model for an artificial neuron.
where the bias \(b\) is sometimes denoted \(w_0\). Here, the signal \(y\) of an artificial neuron is the output of an activation function, which takes as input a weighted sum of signals \(x_1, \dots ,x_n\) received from \(n\) connected artificial neurons.
Conceptually, it is helpful to divide neural networks into four different categories:
general purpose neural networks, including deep neural networks (DNN) with several hidden layers, for supervised learning,
neural networks designed specifically for image processing, the most prominent example of this class being Convolutional Neural Networks (CNNs),
neural networks for sequential data such as Recurrent Neural Networks (RNNs), and
neural networks for unsupervised learning such as Deep Boltzmann Machines.
Artificial neural networks of all these types have found numerous applications in the natural sciences. For example, they have been applied to detect phase transitions in Ising and Potts models, lattice gauge theories, and classify different phases of polymers. They have been used to simulate solutions to numerous differential equations such as the Navier-Stokes equation in weather forecasting. Deep learning has also found interesting applications in quantum physics. For example, in quantum information theory, it has been shown that one can perform gate decompositions with the help of neural networks.
The scientific applications are certainly not limited to the natural sciences. In fact, there is a plethora of applications in essentially all disciplines, from the humanities to life science and medicine. However, the real expansion has been into the tech industry and other private sectors.
Neural network types#
An artificial neural network is a computational model that consists of layers of connected neurons. We will refer to these computational units as nodes.
A wide variety of different kinds of neural networks have been developed. Most of them are constructed with an input layer, an output layer, and hidden layers in between. All layers contain a number of nodes, and connections between nodes are associated with weight variables.
Neural networks (also called neural nets) can be used as nonlinear models for supervised learning. As we will see, neural networks can be viewed as powerful extensions of supervised learning methods such as linear and logistic regression.
Feed-forward neural networks#
The feed-forward neural network (FFNN) was the first and simplest type of artificial neural network that was devised. In this type of network, the information moves in one direction, namely forward through the layers from input to output.
In Fig. 27.1 the nodes are represented by circles, while the arrows display the connections between the nodes and show the direction of information flow. Additionally, each arrow corresponds to a weight variable. In this network, every node in one layer is connected to all nodes in the subsequent layer, making this a so-called fully-connected FFNN.
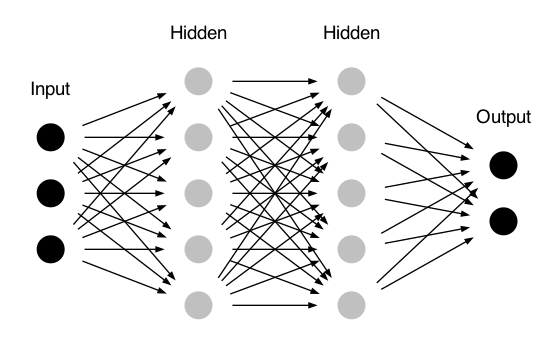
Fig. 27.1 A FFNN with two hidden layers. In addition to the weights associated with the connection arrows there can also be a bias weight connected with each of the active nodes in the hidden and output layers.#
Convolutional Neural Network#
A different variant of FFNNs are convolutional neural networks (CNNs). These networks have a connectivity pattern inspired by the animal visual cortex. Individual neurons in the visual cortex only respond to stimuli from small sub-regions of the visual field, called a receptive field. A similar connectivity of CNNs makes them well-suited to exploit the strong spatial correlations present in images. The response of each node in a CNN is expressed mathematically as a convolution operation.
Convolutional neural networks emulate the behaviour of neurons in the visual cortex by enforcing a local connectivity pattern between nodes of adjacent layers: Each node in a convolutional layer is connected only to a subset of the nodes in the previous layer, in contrast to the fully-connected FFNN. Often, CNNs consist of several convolutional layers that learn local features of the input, with a fully-connected layer at the end, which gathers all the local data and produces the outputs. They have wide applications in image and video recognition.
Recurrent neural networks#
So far we have only mentioned artificial neural networks where information flows only in the forward direction. Recurrent neural networks, on the other hand, have connections between nodes that form directed cycles. This creates a form of internal memory which is able to capture information on what has been calculated before. The output becomes dependent on previous computations. Recurrent neural networks can therefore make use of sequential information. An example of sequential information is sentences, making recurrent neural networks especially well-suited for text and speech recognition.
Feedback networks#
Artificial neural networks that can perform unsupervised learning typically require some sort of feedback mechanism. Two famous examples of feedback networks are Hopfield networks and Boltzmann machines. Due to strong analogies with quantum spin systems, the functionality of these networks can be understood with arguments from statistical physics. John Hopfield and Geoffrey Hinton were awarded the 2024 Nobel Prize in physics for these and related foundational contributions to machine learning with artificial neural networks.
Neural network architecture#
In the following sections we restrict ourselves to fully-connected FFNNs. The term multilayer perceptron is used ambiguously in the literature, sometimes loosely to mean any FFNN, sometimes strictly to refer to networks composed of multiple layers of perceptron nodes (with step-function activation). A general FFNN, however, consists of:
An input layer that distributes the input signals to the active layers.
A multilayer network structure with one or more hidden layers, and one output layer.
the input nodes pass values to the first hidden layer, its nodes pass the information on to the second and so on until the output layer produces the final output.
The number of layers correspond to the network depth. As a convention we primarily count the number of active layers (i.e., those that are associated with activation signals) when specifying the depth. Consequently, we denote a network with one layer of input units plus one layer of hidden units and one layer of output units as a two-layer network. A network with two layers of hidden units is called a three-layer network, etc.
The number of nodes can be different in each layer and is usually known as the layer width. Note, however, the number of nodes in the input and output layers are dictated by the task, or mapping, that the network should perform. For example, a network that is constructed to describe a relation \(y = y(x_1, x_2)\) will have two input nodes and one output node.
The hidden layers are not linked to observables but play an important role in learning and describing complex relations.
Why deep neural networks?#
According to the universal approximation theorem [Cyb89], a feed-forward neural network with just one hidden layer containing a finite number of neurons can approximate a continuous multidimensional function to arbitrary accuracy. The proof of this theorem assumes that the activation function for the hidden layer is a non-constant, bounded and monotonically-increasing continuous function. The theorem thus states that simple neural networks provide flexible models for a wide variety of interesting functions. The multilayer, feedforward architecture has proven to be easier to train and really gives neural networks the potential of being universal approximators.
Limitations of supervised learning with deep networks#
Like all statistical methods, supervised learning using neural networks has important limitations. This is especially important when one seeks to apply these methods to physics problems. As all machine-learning algorithms, neural networks are not a universal solution.
As physicists you should always maintain the ambition of learning about the model itself. Often, the same or better performance on a task can be achieved by identifying the most relevant features.
Here we list some of the important limitations of supervised neural network based models.
Need labeled data. All supervised learning methods require labeled data. Often, labeled data is harder to acquire than unlabeled data (e.g. one must pay for human experts to label images).
Deep neural networks are extremely data hungry. They perform best when data is plentiful. This is extra problematic for supervised methods where the data must also be labeled. The utility of deep neural networks is extremely limited if data is hard to acquire or the datasets are small (hundreds to a few thousand samples). In this case, the performance of other methods that utilize hand-engineered features can exceed that of deep neural networks.
Homogeneous data. Almost all deep neural networks deal with homogeneous data of one type. It is very hard to design architectures that mix and match data types (i.e., some continuous and some discrete variables). In some applications, mixed data types is what is required. So called ensemble models, such as random forests or gradient-boosted trees, are better suited to handle mixed data types.
Many problems are not just about prediction. In the natural sciences we are often interested in learning about the underlying process that generates the data. In this case, it is often difficult to cast hypotheses in a supervised learning setting. While the problems are related, it is possible to make good predictions with a wrong model. The model might or might not be useful for understanding the underlying scientific principles.